

OpenWAM: An Open, Modular Exploration towards Systematic World-Action Model Pretraining
TAG@CoRL 2026Best Paper Award
A systematic project on world-action models across infrastructure, studies, and models.
I am a third-year Ph.D. student in Computer Science and Engineering (CSE) at The Chinese University of Hong Kong (CUHK), advised by Prof. Pheng-Ann Heng and Prof. Chi-Wing Fu, Philip.
I am dedicated to advancing General and Scalable Multimodal Intelligence. Recently, I focus on training Generative Foundation Models (Qwen-Image-Series and OmniShow), while also exploring Embodied AI (OpenWAM and PackLab) and Agentic Systems and Evaluation (UniWeaver and MMDeepResearch-Bench). Ultimately, I aim to build AI that can understand, align with, and act on human intention, and in turn shape the world.
If you would like to discuss potential opportunities for collaboration, please feel free to contact me.
OpenWAM is accepted by TAG@CoRL 2026 and selected as the Best Paper.
MM-BrowseComp is accepted by EMNLP 2026.
OmniShow is accepted by ICML 2026.
HiFi-Inpaint is accepted by CVPR 2026.
IdentityStory is accepted by AAAI 2026.
SceneDecorator, BlindFormer, and CellVerse are accepted by NeurIPS 2025.
OmniMol is accepted by Nature Communications.
TRIG is accepted by ICCV 2025.
MoIE is early accepted by MICCAI 2025 as a spotlight.
MagicTailor is accepted by IJCAI 2025 as an oral.
MM-Mixing is accepted by AAAI 2025.
Dual-Schedule Inversion is accepted by WACV 2025 as an oral.
IFAST is accepted by IEEE TIFS 2024 (a CCF-A journal).
I am selected as an Outstanding Graduate of Beijing.
I am awarded a Postgraduate National Scholarship.
RepMode is selected as a CVPR Highlight (Top 2.6%).
RepMode is accepted by CVPR 2023.
EM Loss is accepted by ECCV 2022.
I am awarded an Undergraduate National Scholarship.
Scroll to see more ↓
* Equal Contribution · † Project Lead
OpenWAM Team (Donghao Zhou as core contributor)
TAG@CoRL 2026Best Paper Award
A systematic project on world-action models across infrastructure, studies, and models.
Donghao Zhou*, Guisheng Liu*, Hao Yang, Jiatong Li, Jingyu Lin, Xiaohu Huang, Yichen Liu, Xin Gao, Cunjian Chen, Shilei Wen, Chi-Wing Fu, Pheng-Ann Heng
ICML 2026
The first all-in-one model for Human-Object Interaction Video Generation.
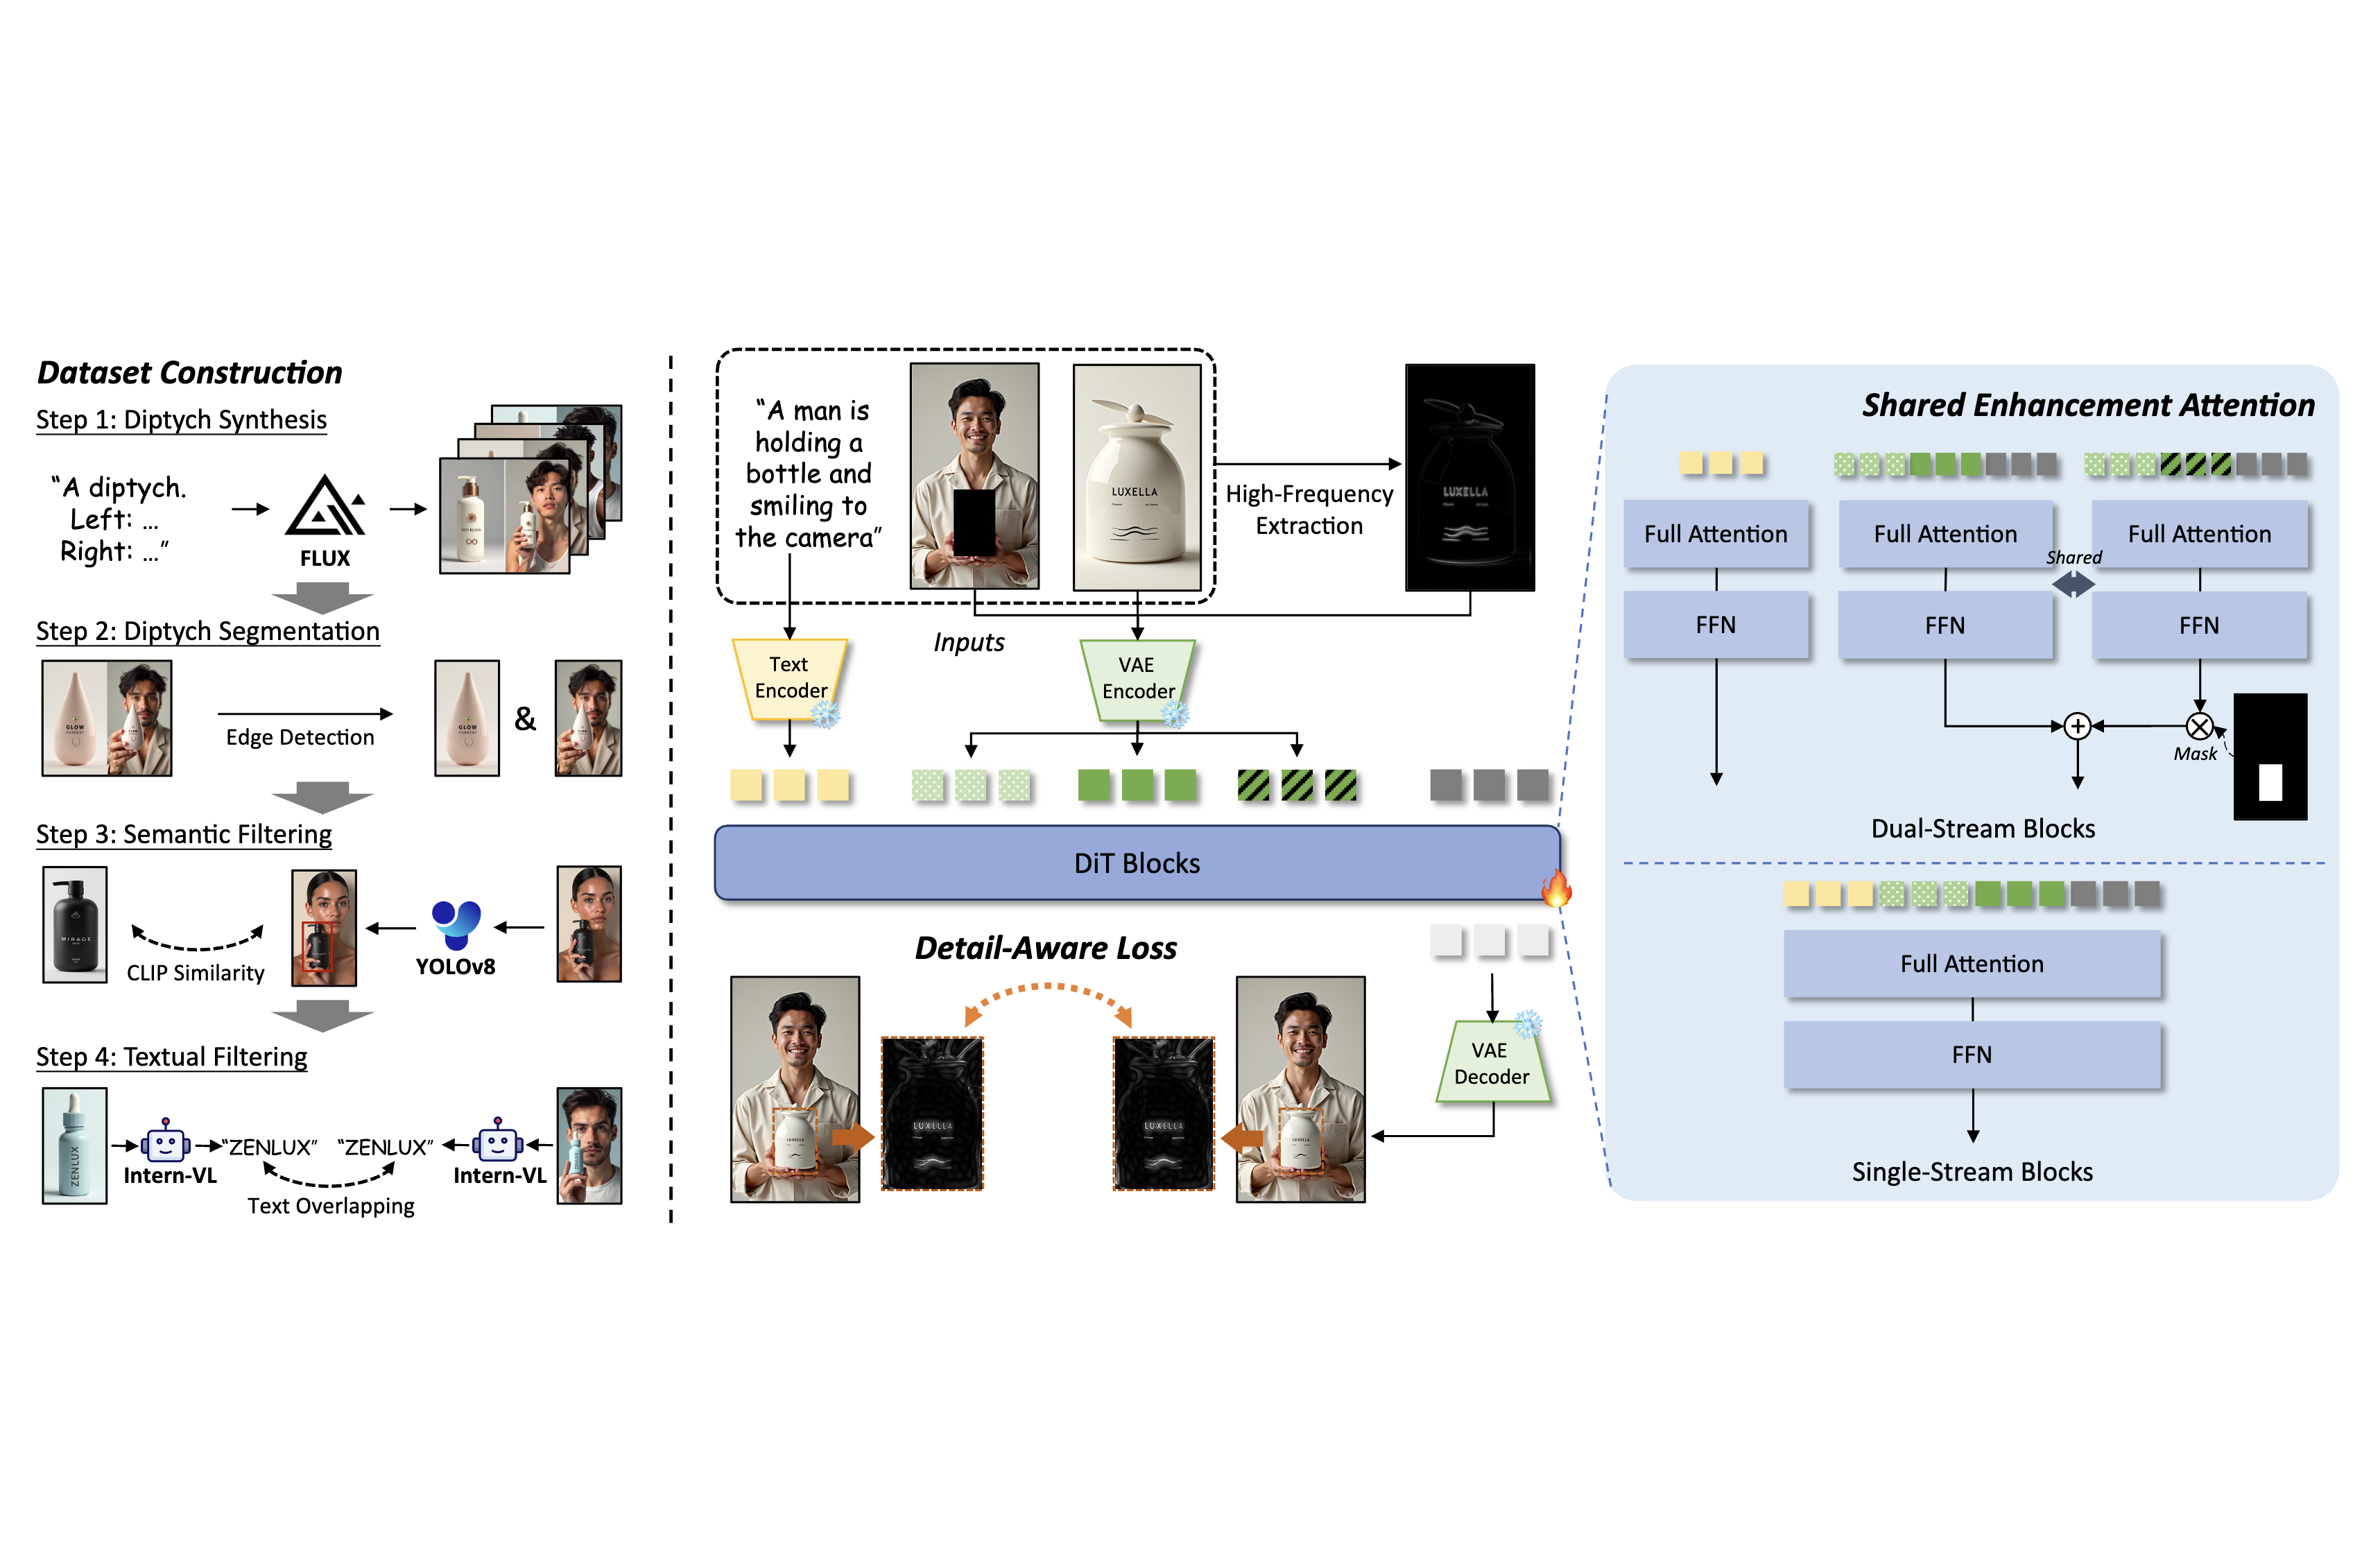
Yichen Liu*, Donghao Zhou*, Jie Wang, Xin Gao, Guisheng Liu, Jiatong Li, Quanwei Zhang, Qiang Lyu, Lanqing Guo, Shilei Wen, Weiqiang Wang, Pheng-Ann Heng
CVPR 2026
An inpainting model supervised on high-frequency detail to maintain reference consistency.
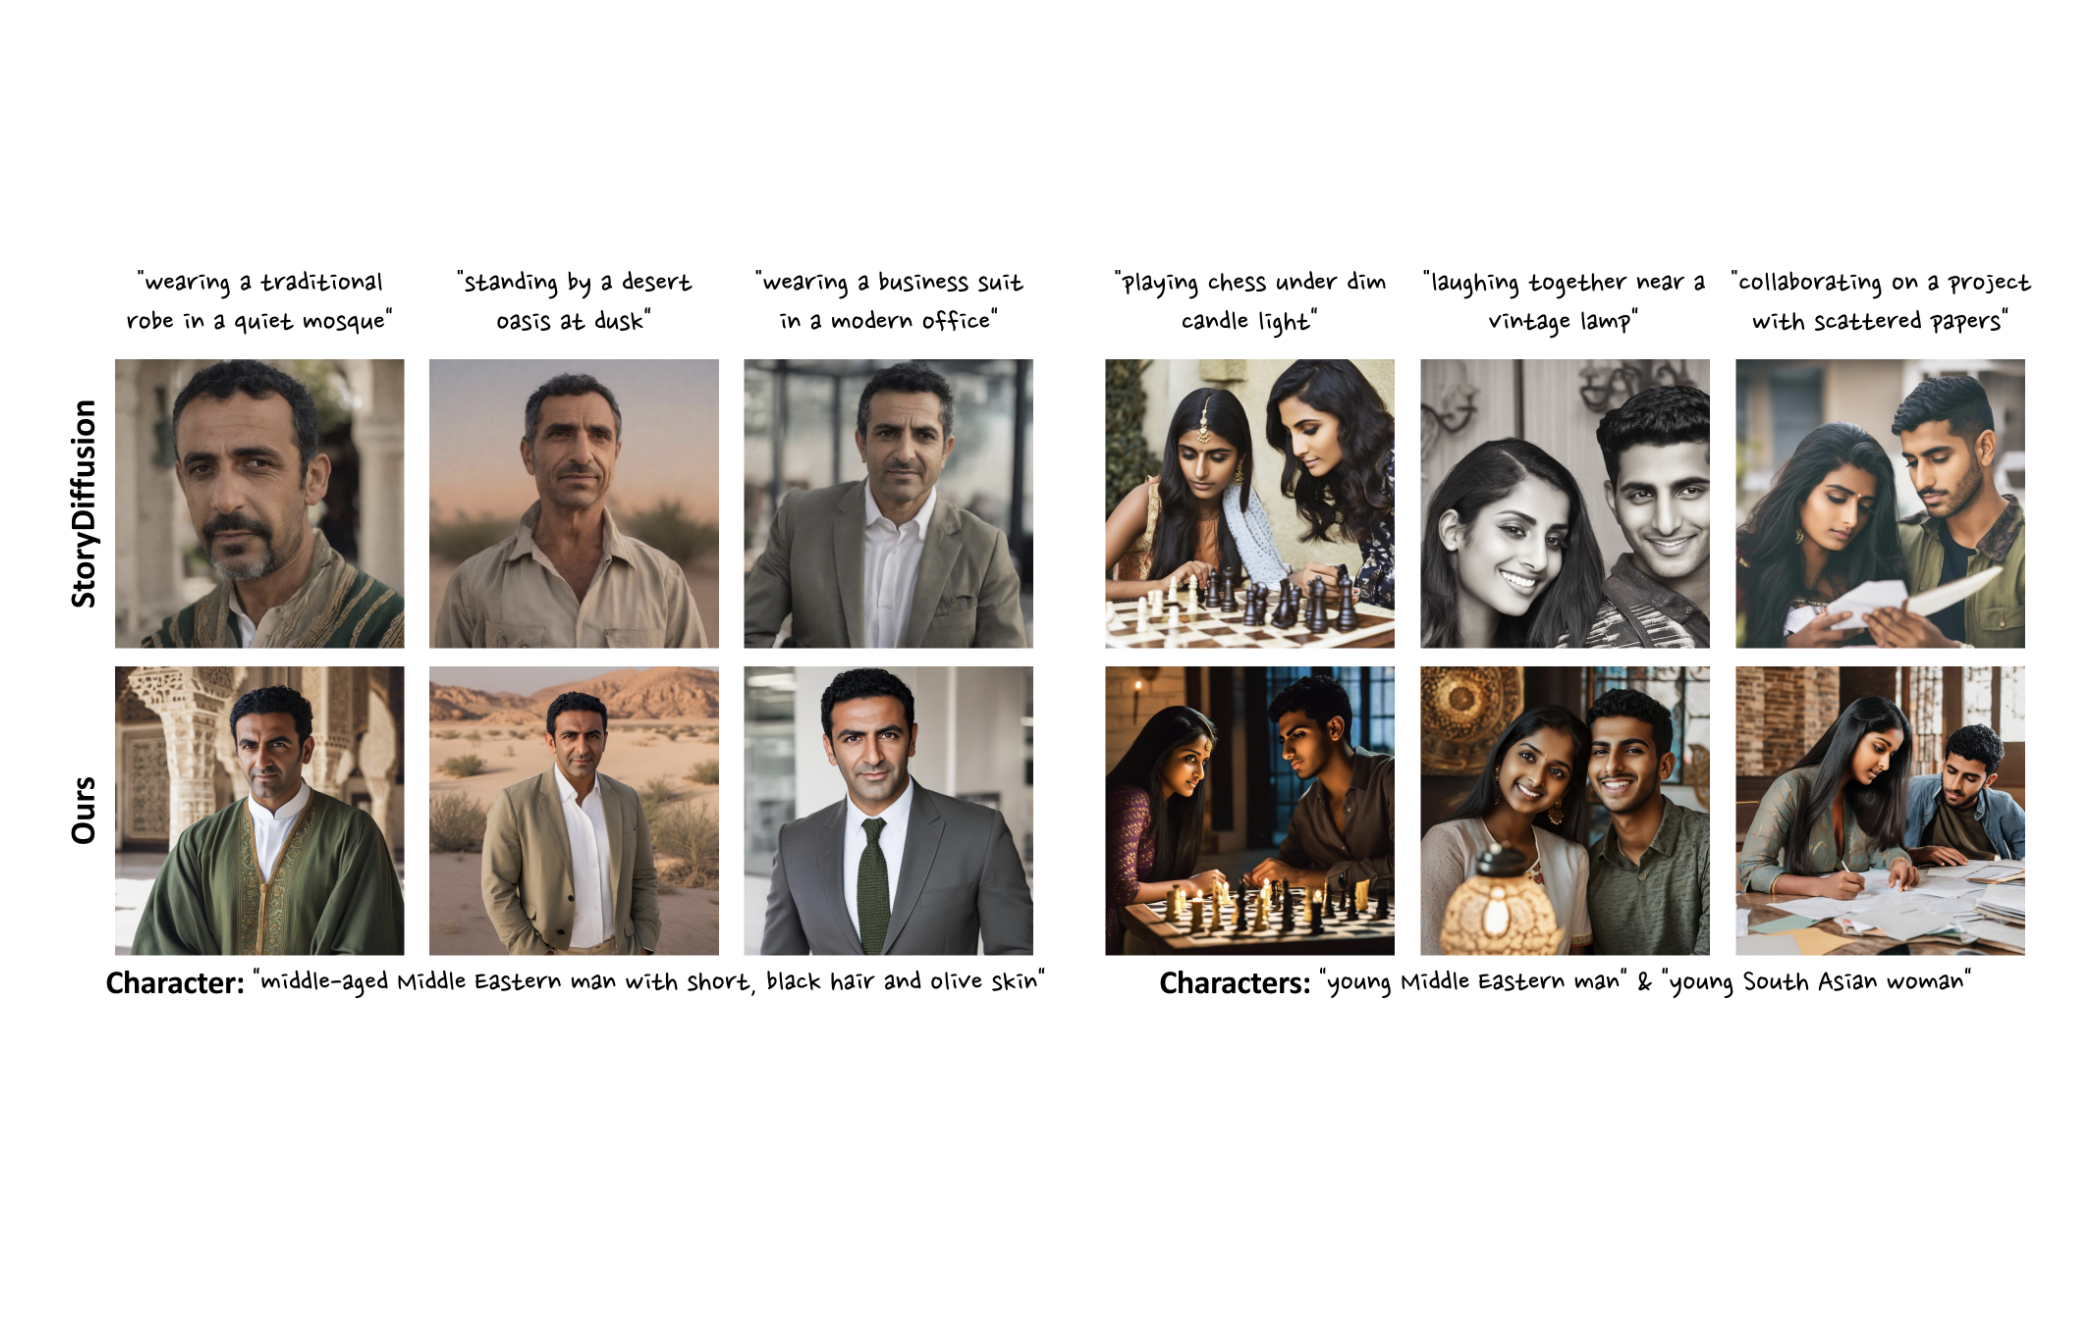
Donghao Zhou*, Jingyu Lin*, Guibao Shen, Quande Liu, Jialin Gao, Lihao Liu, Lan Du, Cunjian Chen, Chi-Wing Fu, Xiaowei Hu, Pheng-Ann Heng
AAAI 2026
A plug-and-play framework that turns text alone into a series of consistent character images.
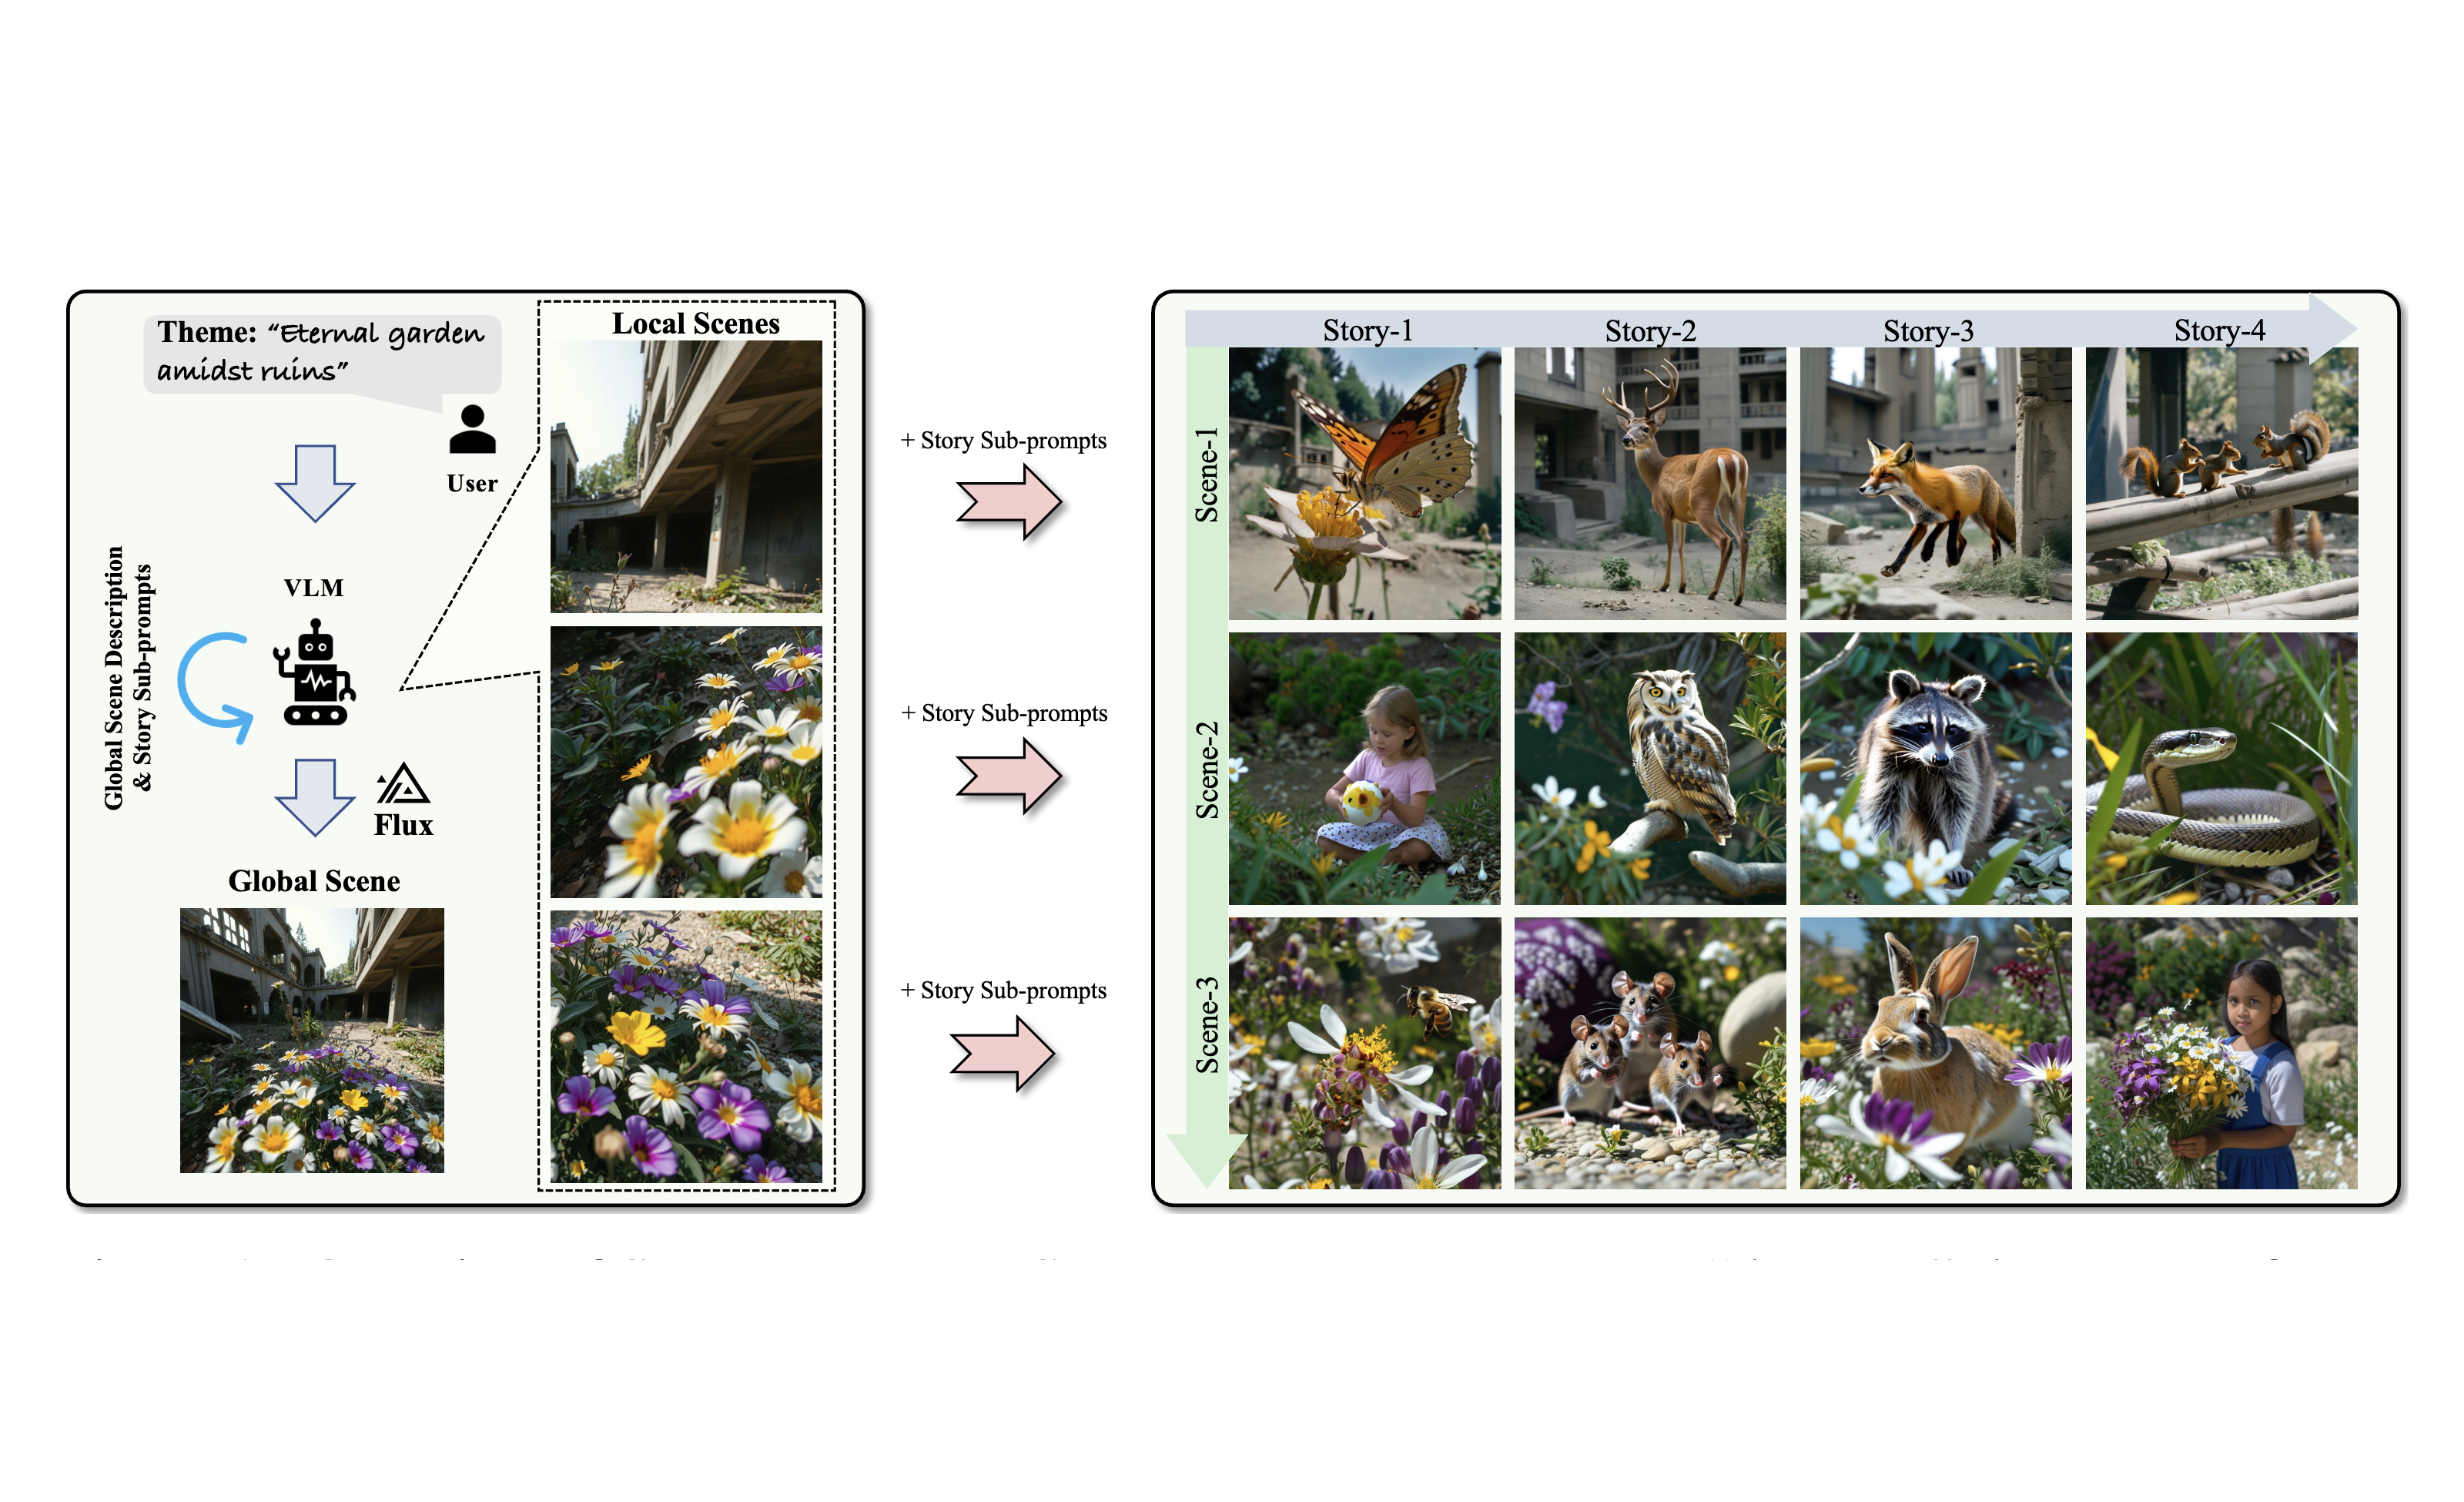
Quanjian Song*, Donghao Zhou*†, Jingyu Lin*†, Fei Shen, Jiaze Wang, Xiaowei Hu, Cunjian Chen, Pheng-Ann Heng
NeurIPS 2025
An agentic framework pioneering scene-oriented visual story generation.
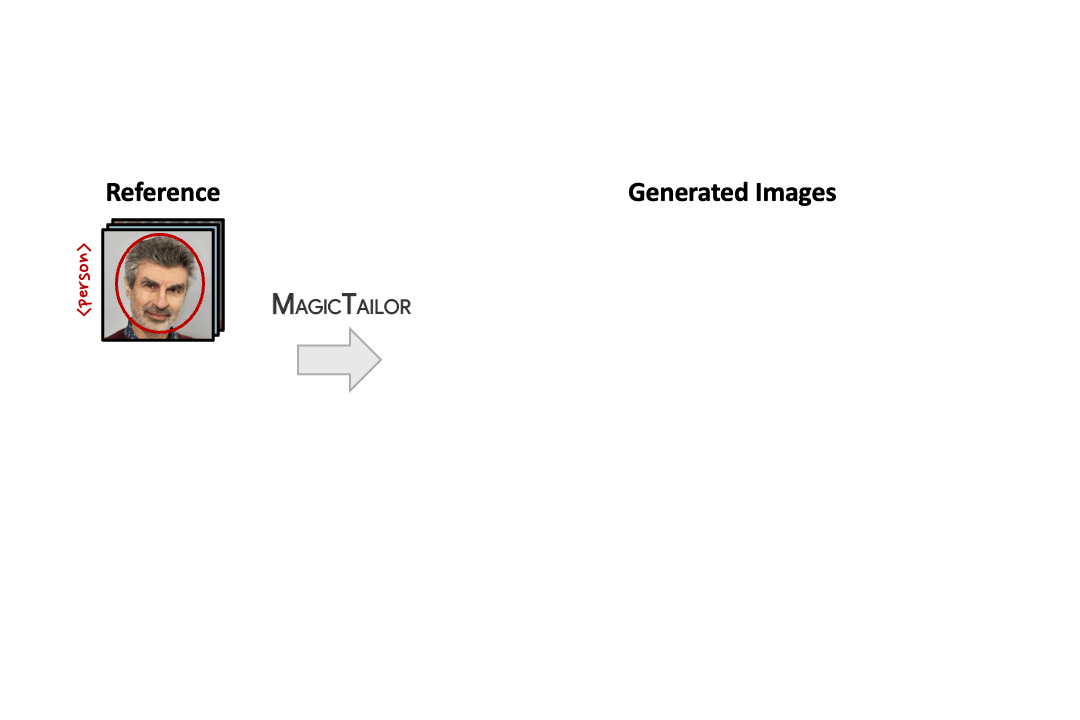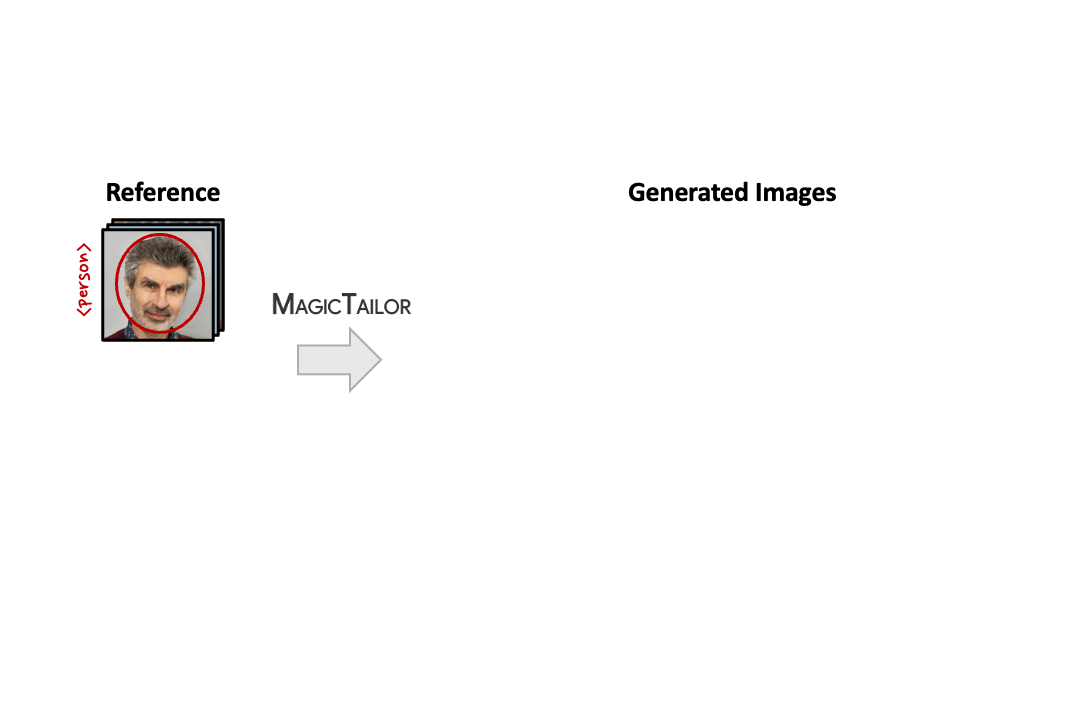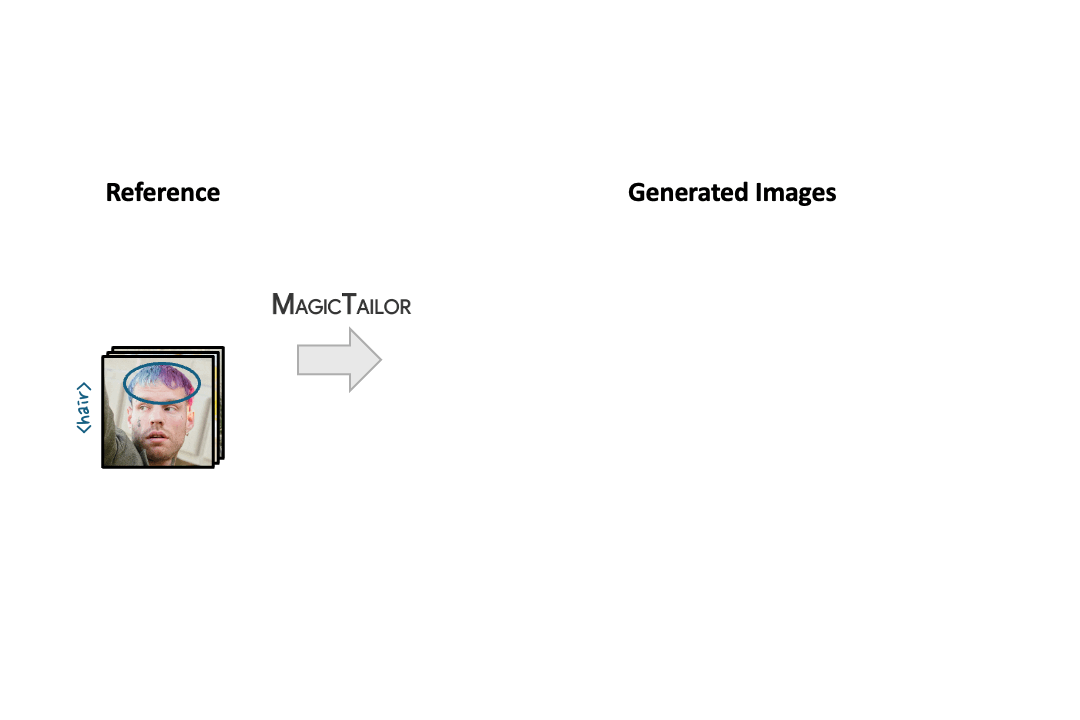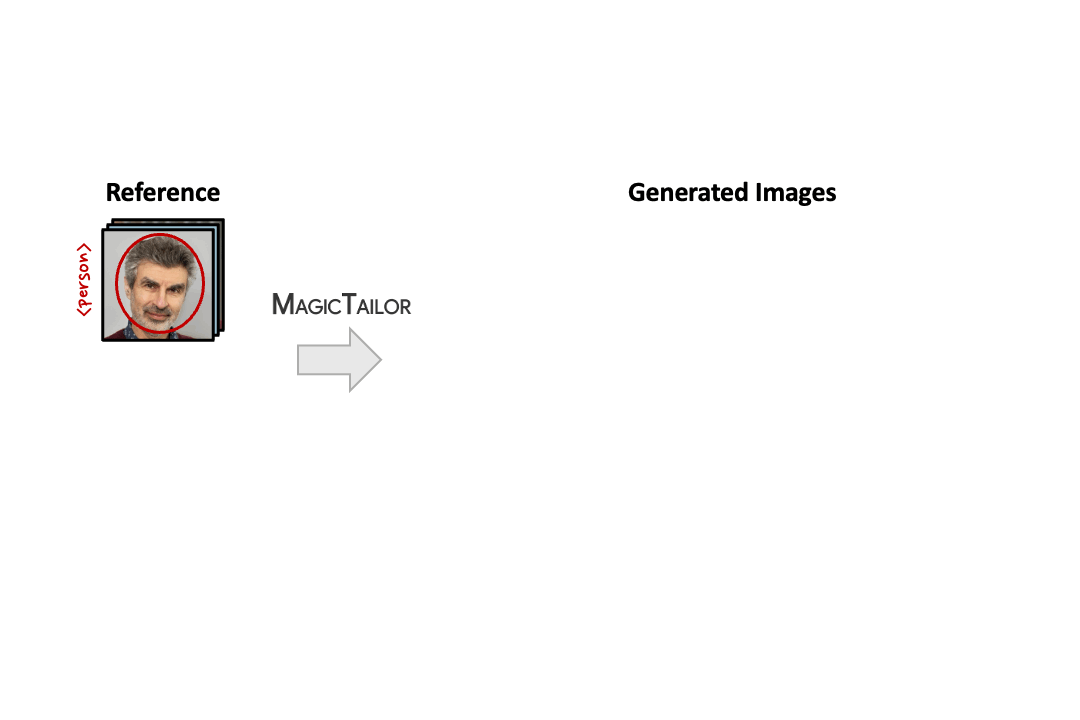
Donghao Zhou*, Jiancheng Huang*, Jinbin Bai, Jiaze Wang, Hao Chen, Guangyong Chen, Xiaowei Hu, Pheng-Ann Heng
IJCAI 2025Oral
The first to achieve component-controllable personalization in text-to-image models.
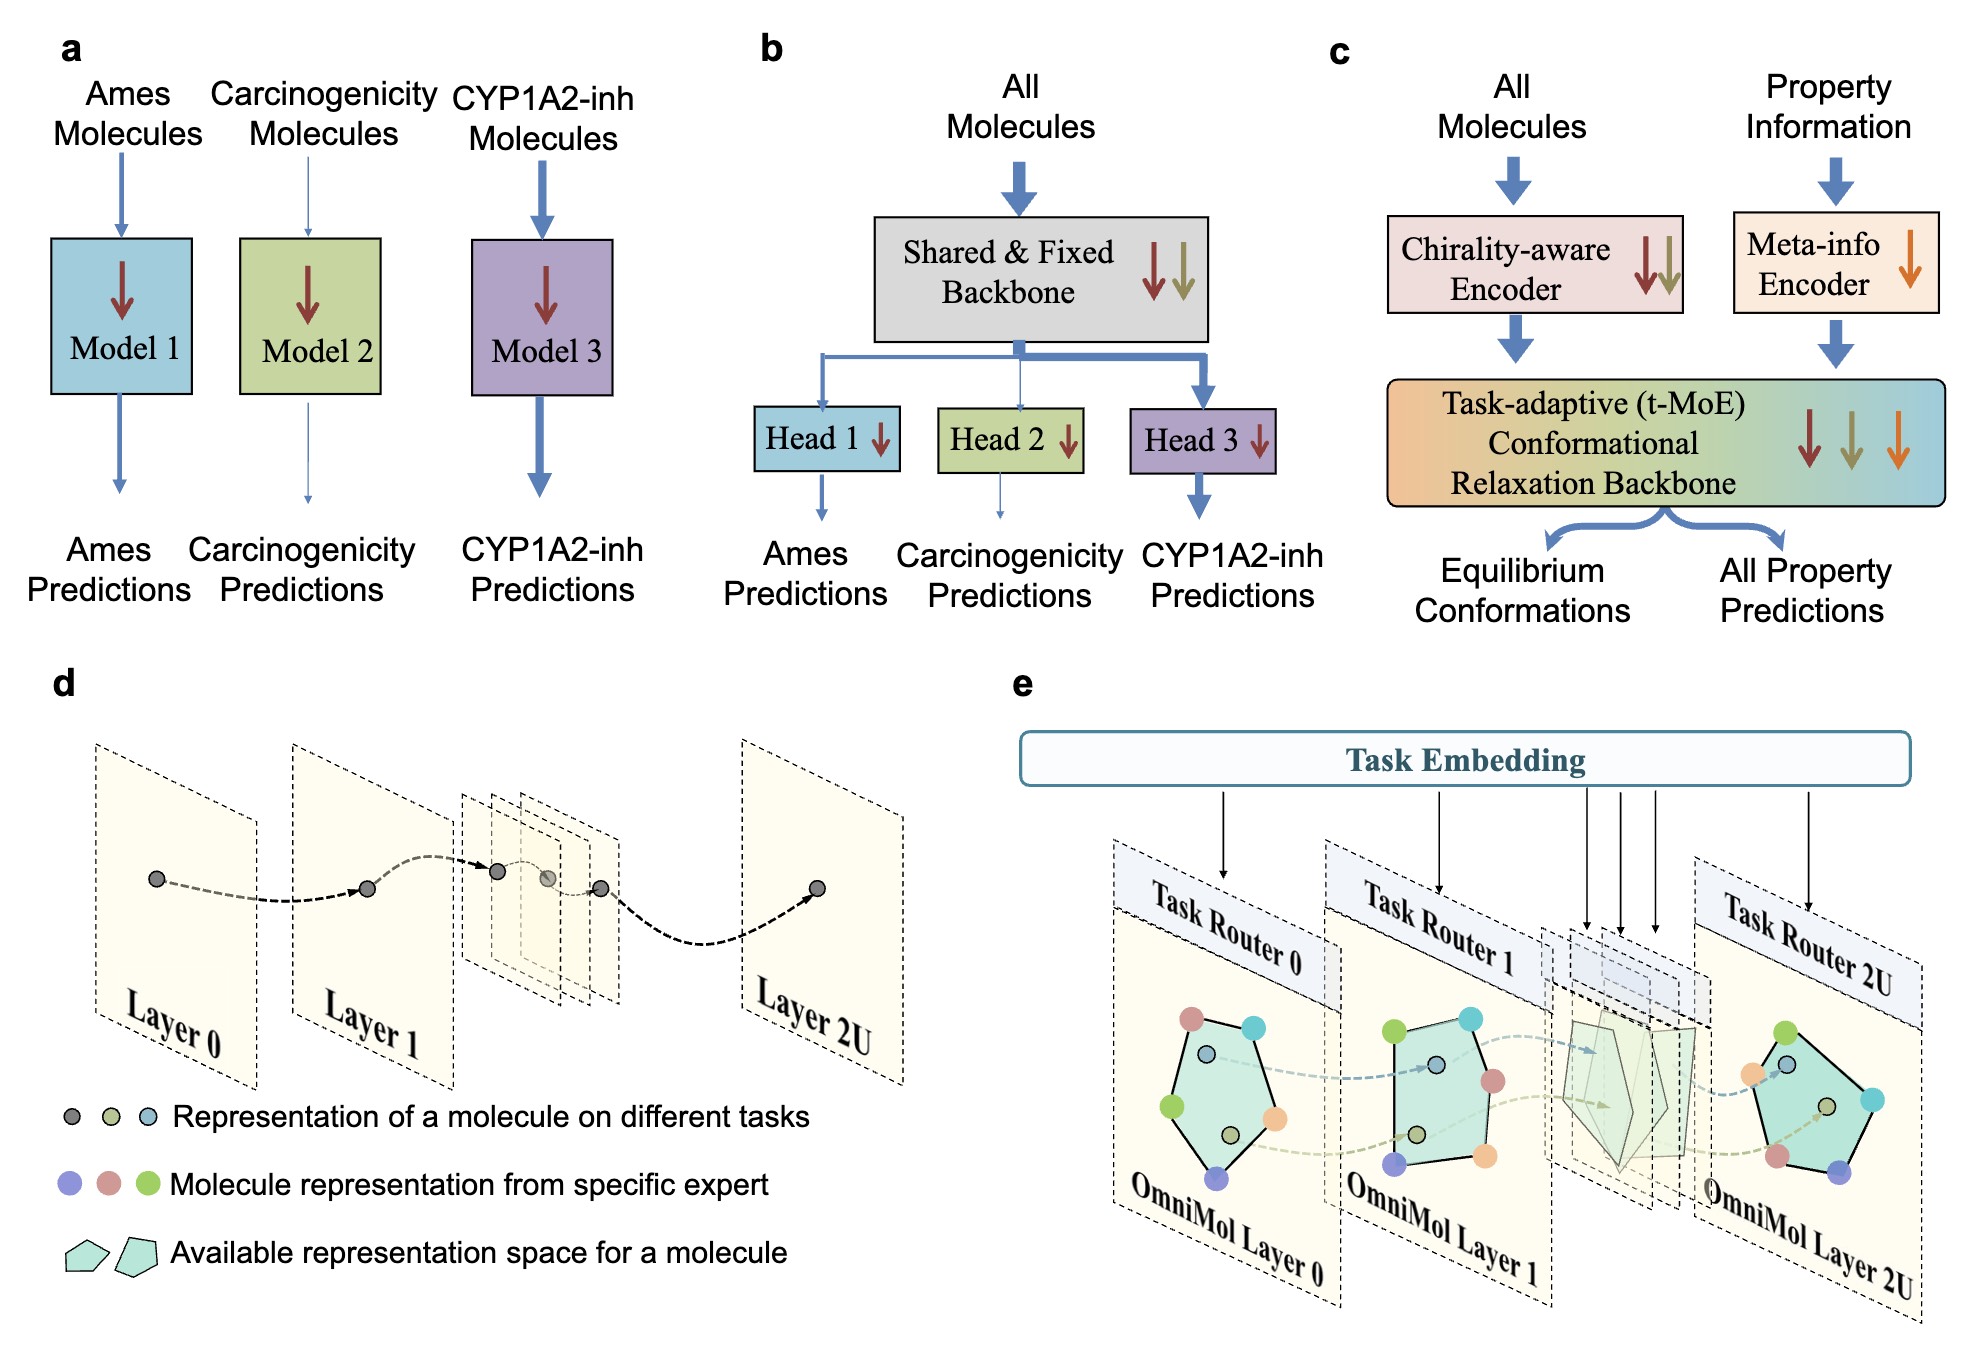
Bowen Wang, Junyou Li, Donghao Zhou, Lanqing Li, Jinpeng Li, Ercheng Wang, Jianye Hao, Liang Shi, Chengqiang Lu, Jiezhong Qiu, Tingjun Hou, Dongsheng Cao, Guangyong Chen, Pheng-Ann Heng
Nature Communications 2025
A unified foundation model for molecular representation learning from imperfect annotations.
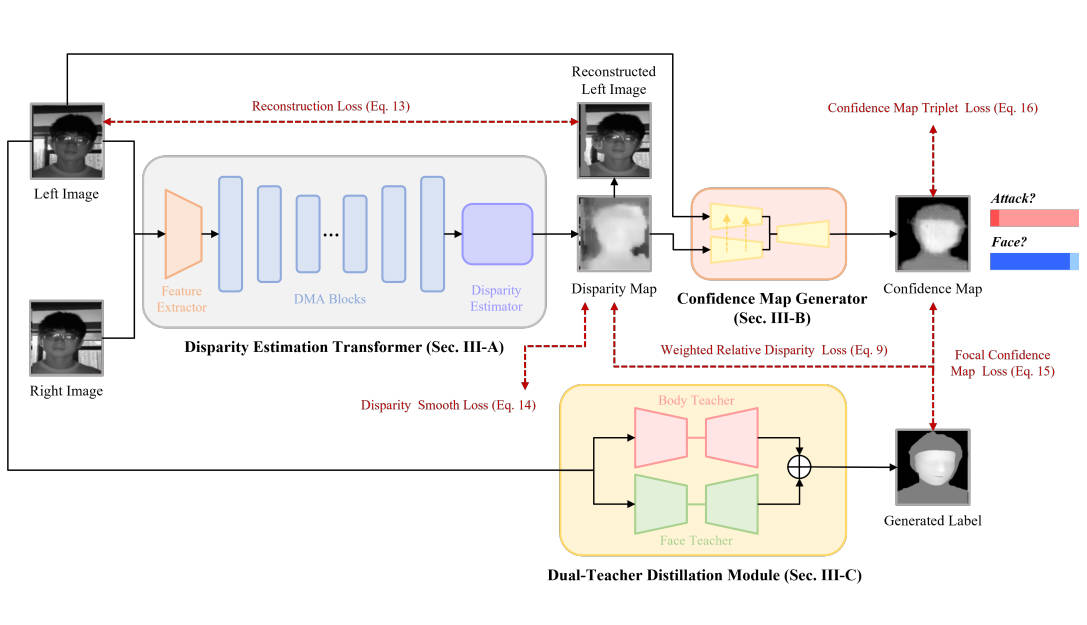
Jiancheng Huang*, Donghao Zhou*, Jianzhuang Liu, Linxiao Shi, Shifeng Chen
TIFS 2024CCF-A Journal
An anti-spoofing model that learns facial depth without any pixel-level depth annotation.
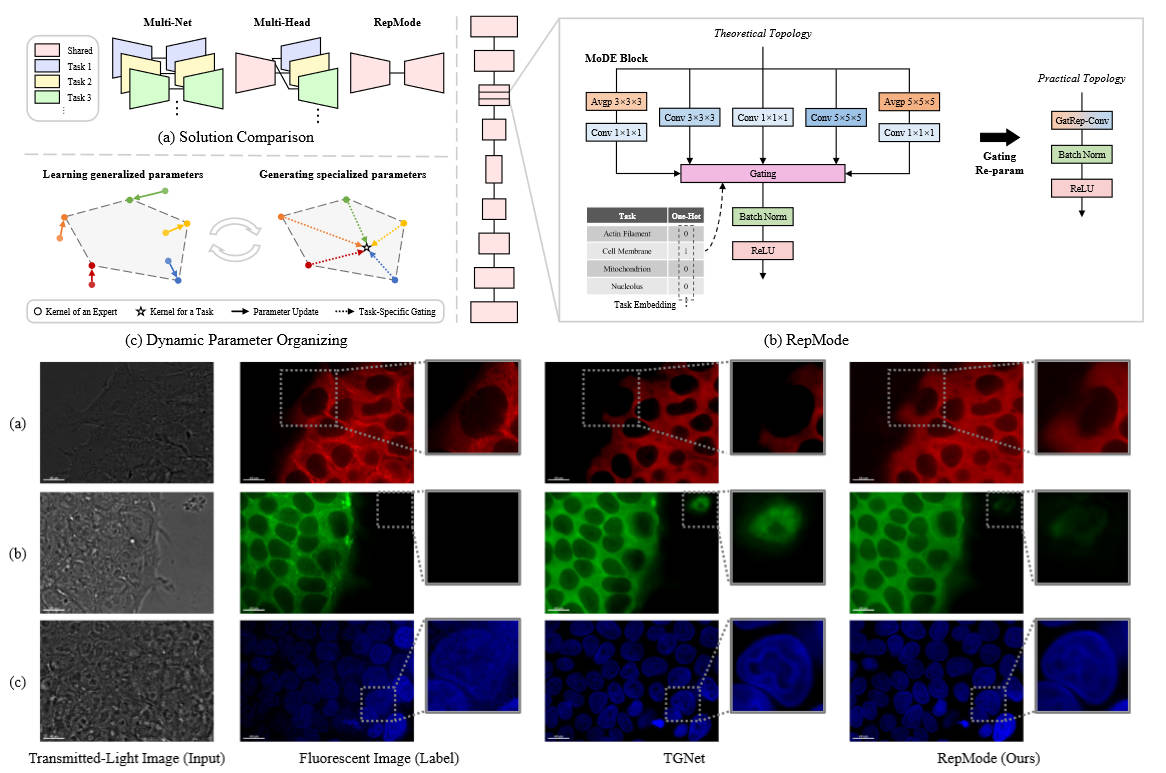
Donghao Zhou, Chunbin Gu, Junde Xu, Furui Liu, Qiong Wang, Guangyong Chen, Pheng-Ann Heng
CVPR 2023Highlight (Top 2.6%)
A mixture-of-experts model for subcellular prediction, re-parameterized into per-task weights.
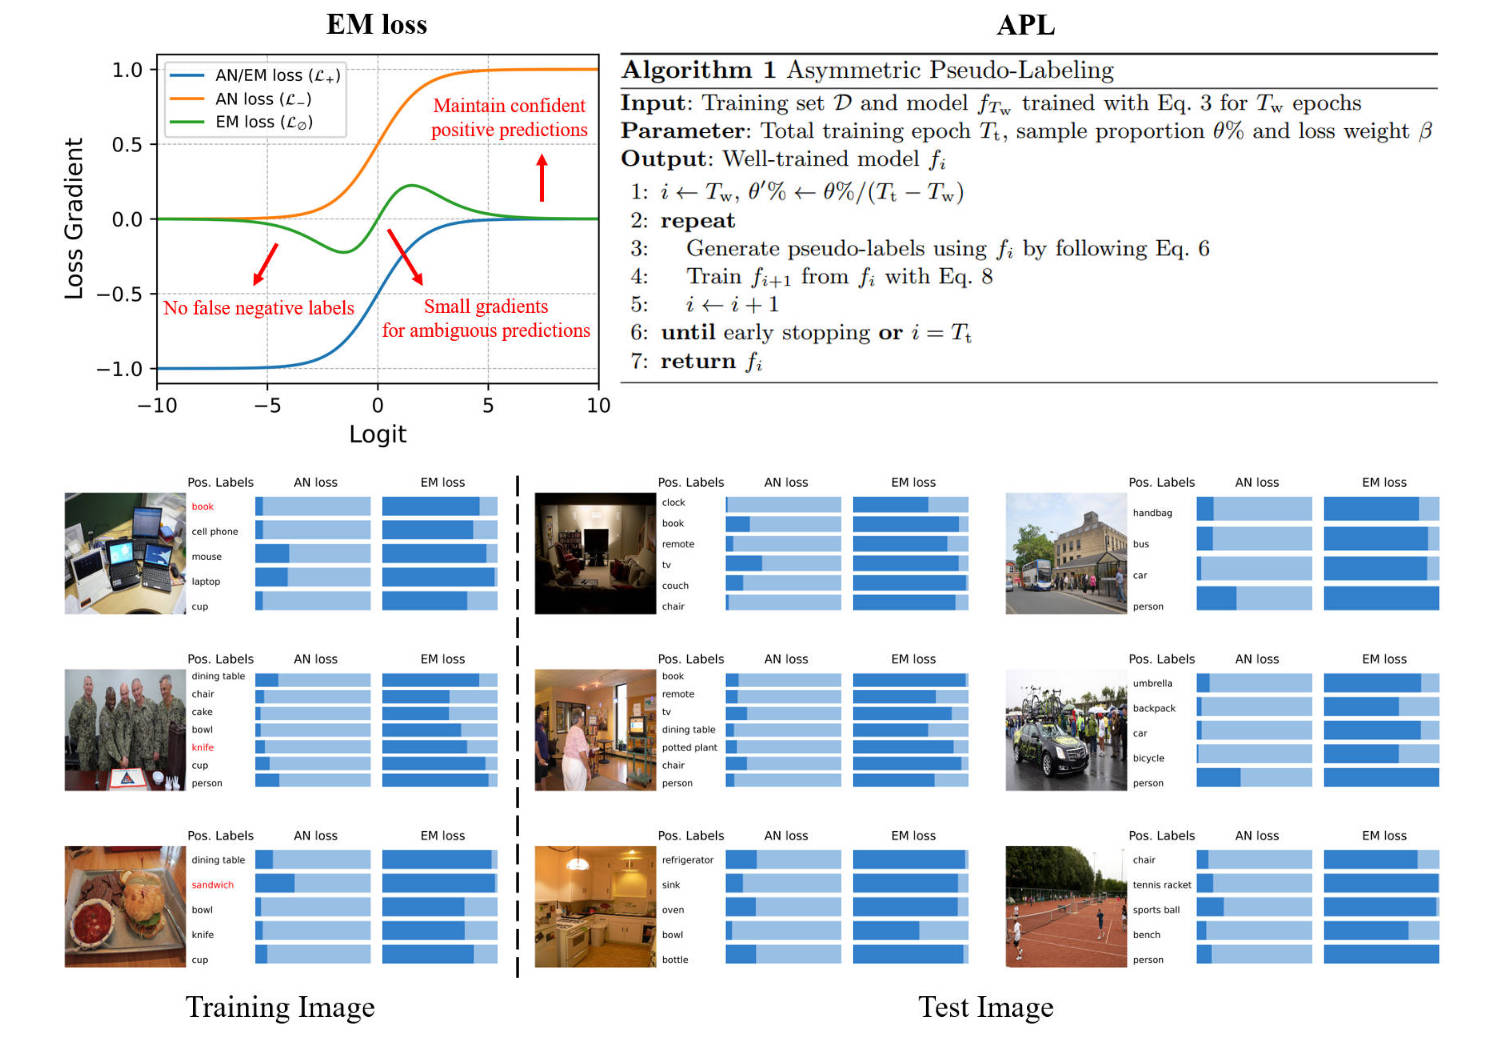
Donghao Zhou, Pengfei Chen, Qiong Wang, Guangyong Chen, Pheng-Ann Heng
ECCV 2022
Rethinking unannotated labels as unknown for single-positive multi-label learning.
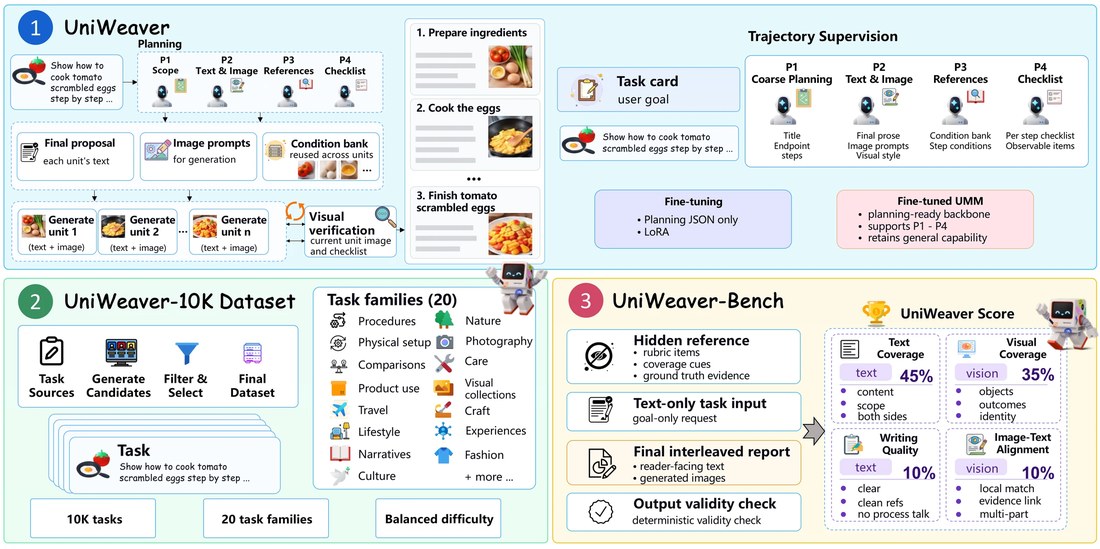
Hongxu Chen*, Zixuan Zhong*, Donghao Zhou*†, Haodong Li, Xiaomin Yu, Tianhao Li, Shiyao Yu, Zhongwei Wan, Pheng-Ann Heng
arXiv Preprint
A model-agnostic harness unlocking unified multimodal models for interleaved generation.
Donghao Zhou*, Jia-Hui Pan*, Fan Zhang, Xingyuan Bu, Shilong Li, Xiaojie Gao, Yun-Hui Liu, Chi-Wing Fu, Pheng-Ann Heng
arXiv Preprint
Bringing multimodal LLMs to closed-loop robotic bin packing, end to end.
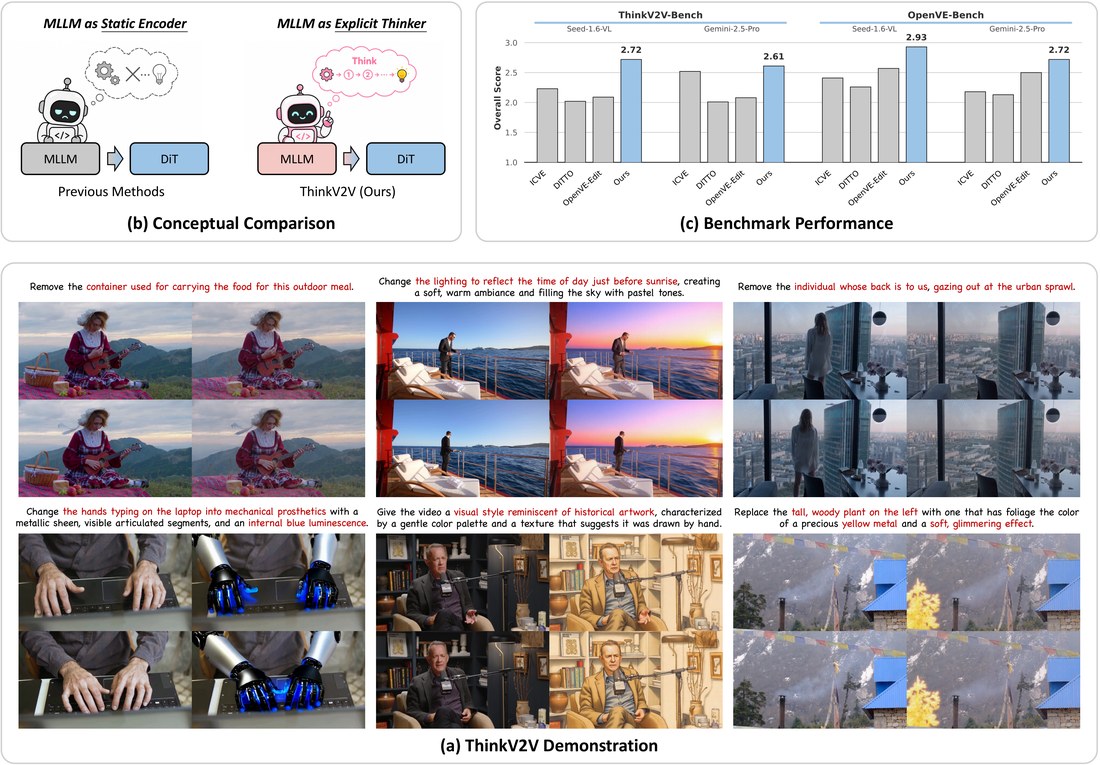
Donghao Zhou*, Haoyang He*, Fan Zhang, Hao Yang, Guisheng Liu, Xin Gao, Zhongwei Wan, Xingyuan Bu, Jie Wang, Qiangpeng Yang, Shilei Wen, Chi-Wing Fu, Pheng-Ann Heng
arXiv Preprint
A reasoning-driven framework that turns MLLM thinking into instruction-guided video edits.
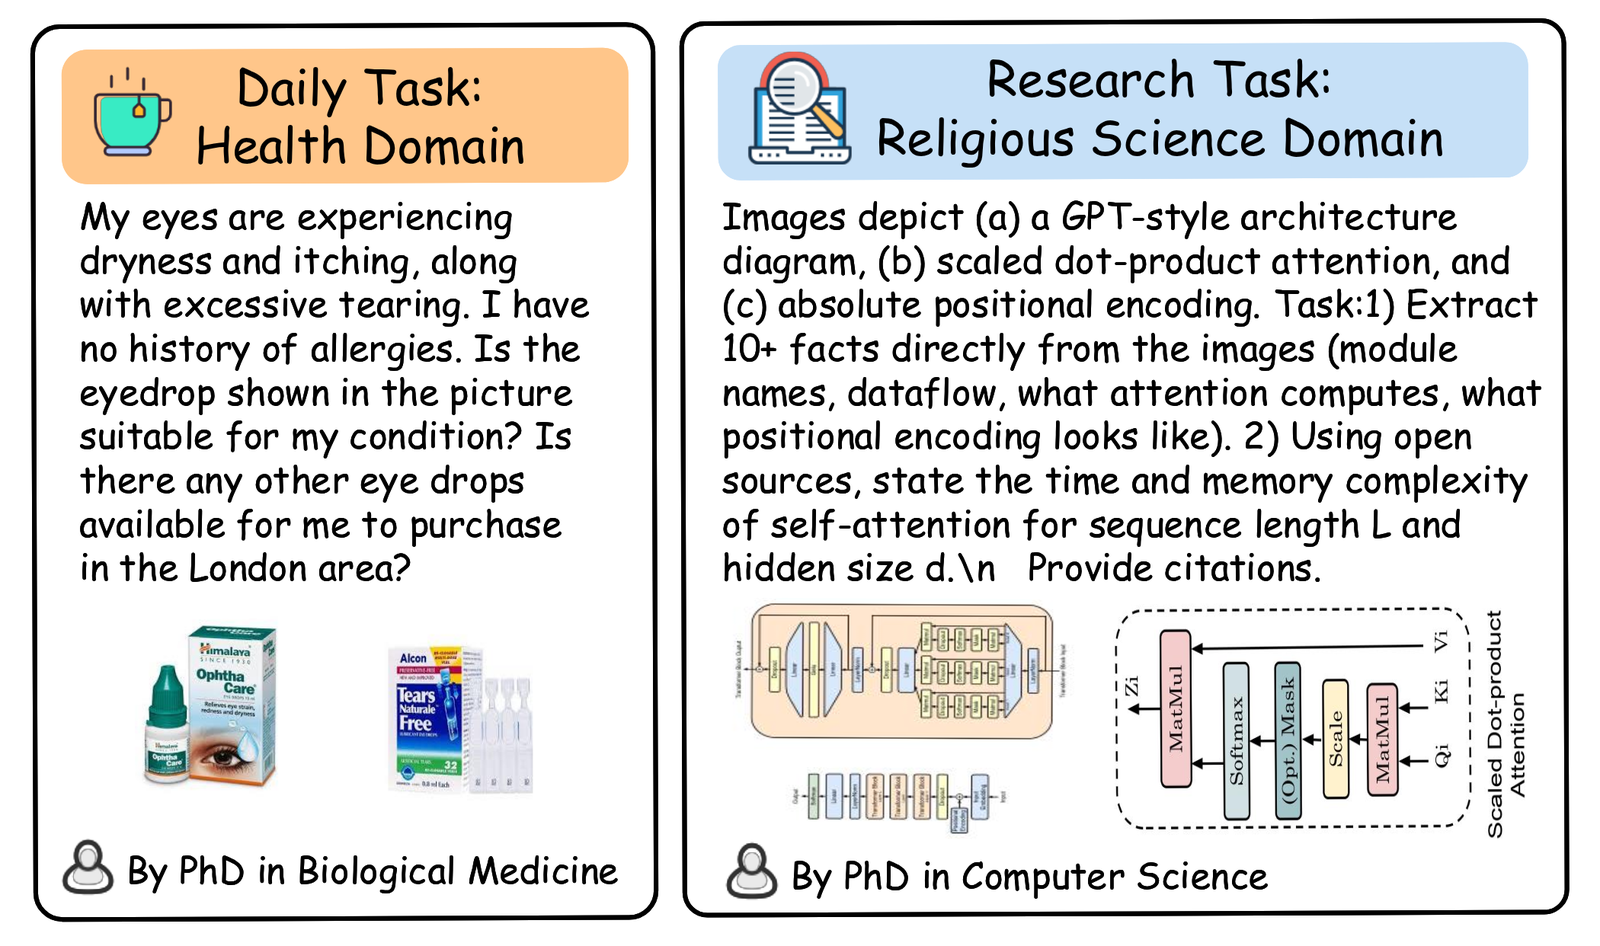
Peizhou Huang*, Zixuan Zhong*, Zhongwei Wan*, Donghao Zhou*, Samiul Alam, Xin Wang, Zexin Li, Zhihao Dou, Li Zhu, Jing Xiong, Chaofan Tao, Yan Xu, Dimitrios Dimitriadis, Tuo Zhang, Mi Zhang
arXiv Preprint
The first benchmark for multimodal deep research agents on image-grounded, cited reports.
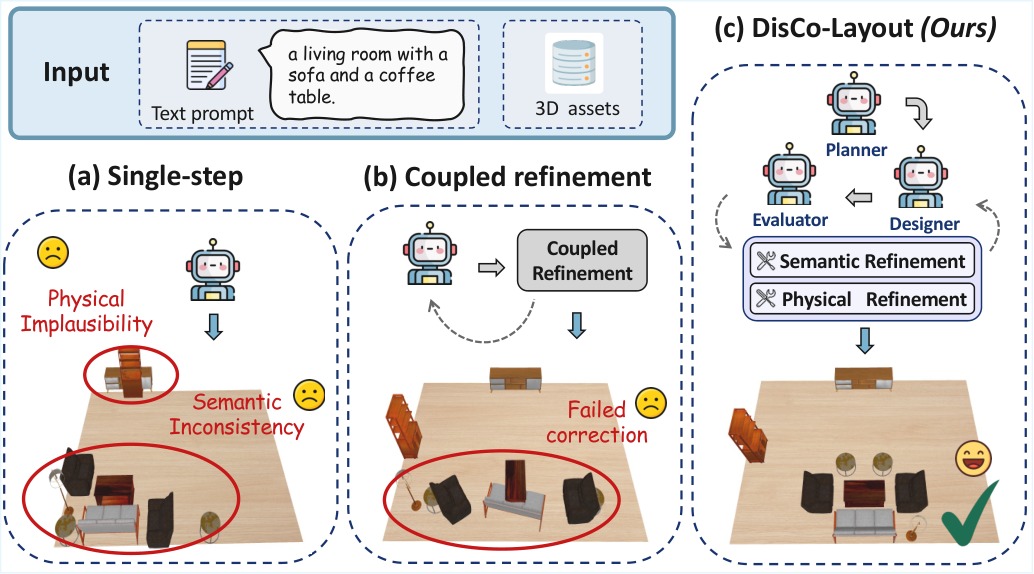
Jialin Gao*, Donghao Zhou*, Mingjian Liang*, Lihao Liu, Chi-Wing Fu, Xiaowei Hu, Pheng-Ann Heng
arXiv Preprint
A multi-agent framework that decouples semantics from physical feasibility in 3D layouts.